Domain-Based Auto-Archiving System
A university project that reads scanned Arabic documents into structured records: OpenCV cleanup, Tesseract OCR, and Solr fuzzy search to correct the results.
Updated .
- Role
- Core Developer
- Year
- 2020
- Type
- University Project
- Stack and skills
- Java, OpenCV, Tesseract OCR, Solr, Marvin Framework
A junior project at Arab International University. The system reads scanned Arabic documents and stores their fields as records, so nobody types them in by hand. I wrote the core logic, and my teammates built the interface and the integration.
Role: Core developer.
Stack: Java, OpenCV, Marvin Framework, Tesseract OCR, Solr.
What it does
- OpenCV cleans each scan first: binarization, skew detection, and noise removal.
- The Marvin Framework finds the text regions, and Tesseract reads them.
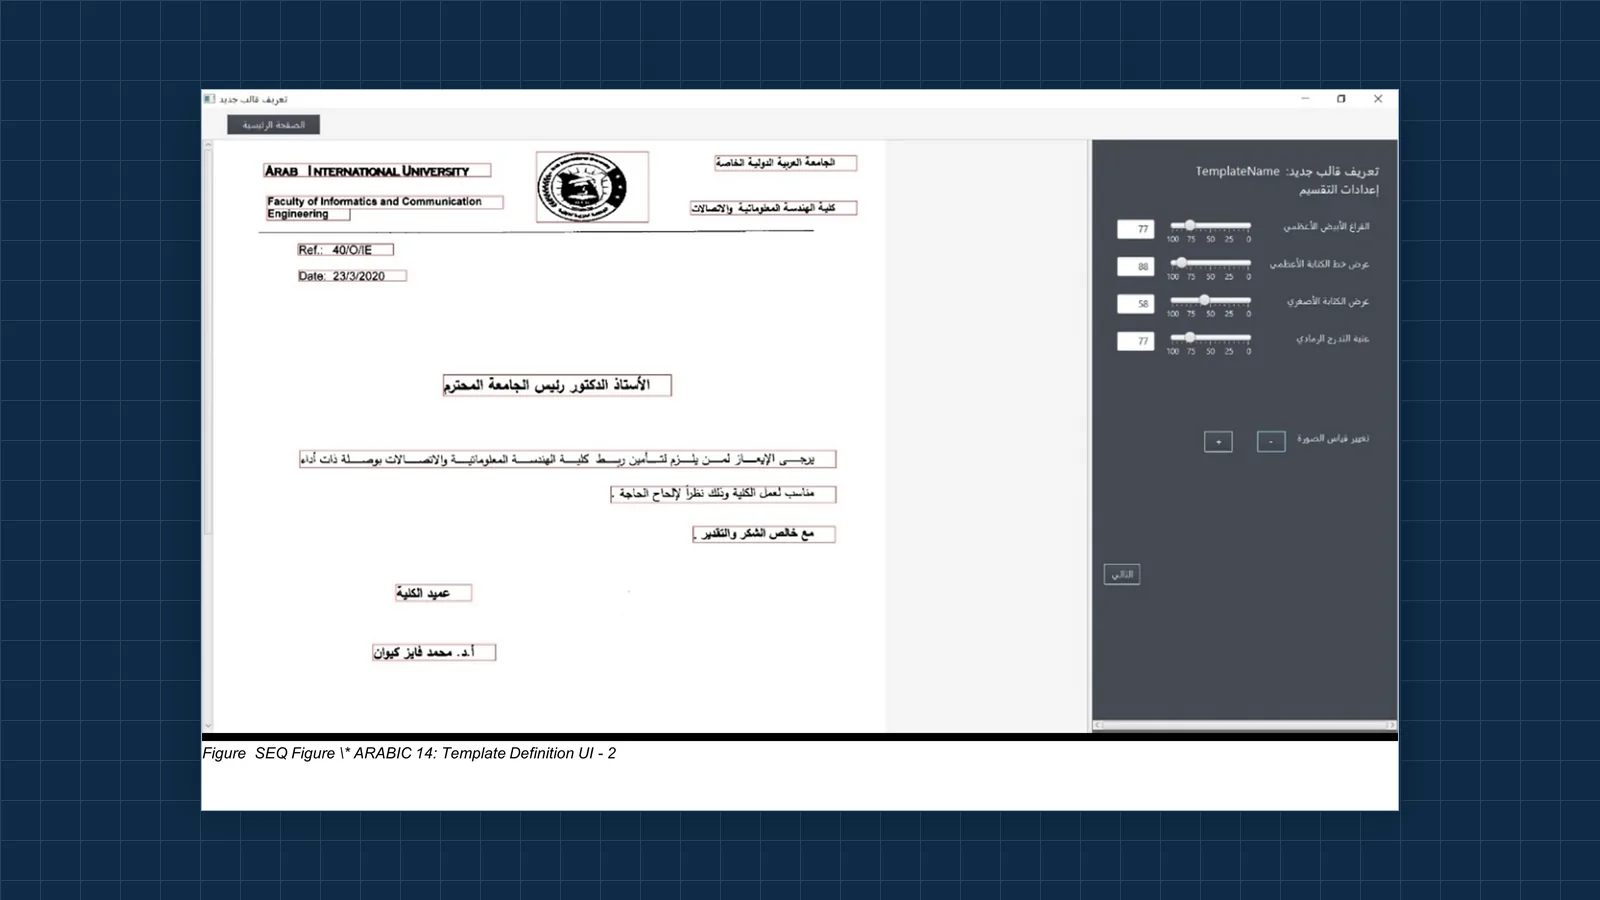
- Templates describe each document layout, so the system knows which region holds which field.
- Solr fuzzy search matches each extracted value against known values, which corrects OCR errors.